Predictive maintenance data for European OEMs: where it’s stored, how it moves, and how it stays secured
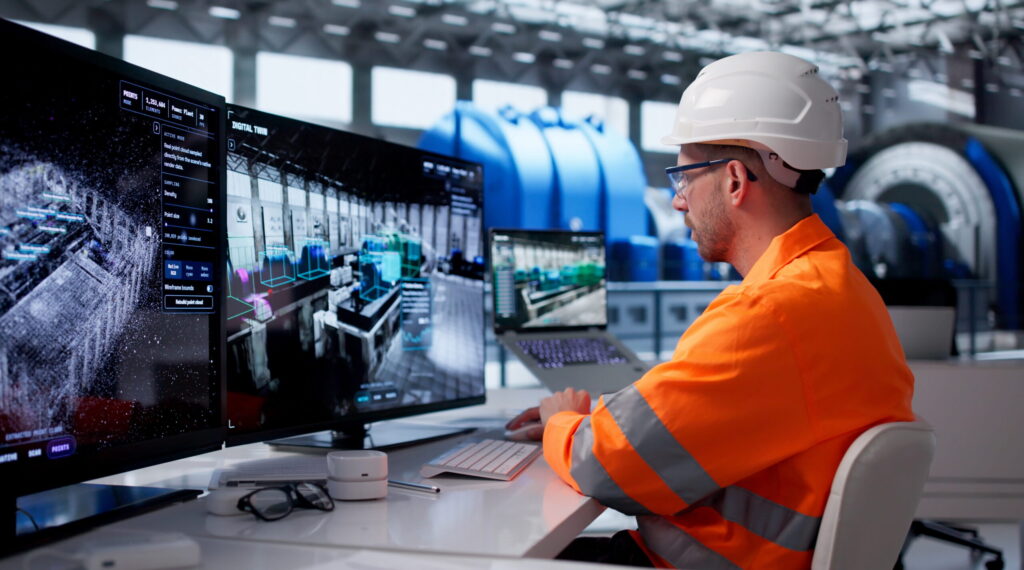
Fleet telemetry is now one of the most valuable assets an OEM owns, and the infrastructure decisions behind it can be difficult to reverse. This article walks through four architectural choices that determine how reliably your predictive maintenance performs over time: where your fleet data lives, how raw sensor signals turn into maintenance action, why AI should advise rather than control, and which security and safety standards should underpin the platform. It closes with a brief look at how the EU’s Cyber Resilience Act, NIS2, Machinery Regulation, and Data Act fit into that picture.
Your fleet is talking, but who is listening?
Every machine you ship generates a continuous stream of data: vibration, temperature, load cycles, fault codes, location, operating hours. Across a fleet of thousands of units operating in mines, ports, warehouses and building entrances, this data becomes one of your company’s most valuable assets.
That data has to travel. It moves from machines to gateways, from gateways to a platform, and from the platform to your service teams, your ERP system, and increasingly your customers and partners. At every stage, the same three questions arise: the same three questions. Where is the data physically stored? Who can reach it? Can you demonstrate that it’s secure?
Discussions about predictive maintenance often begin with algorithms. We think they should start with architecture, for a simple reason: you can replace a model in weeks, but you may depend on a platform’s infrastructure for a decade. Decisions about hosting, integration, and security tend to be made early, under pressure to deliver, and can later become costly and difficult to reverse.
The sections that follow focus on four architectural decisions that matter most for OEMs: where the data lives, how raw signals become action, what role AI should play, and which standards the platform is built to. Regulation comes last by design. Good architecture handles most of it as a side effect.
Sovereignty & infrastructure: where does the data actually sit?
“Data sovereignty” is often treated as a legal concept. For an engineering team, it’s also a practical consideration: can you choose where fleet data from physical assets is stored and processed (including real-time data used to determine maintenance needs, keep operations running smoothly, and help prevent equipment failures)? And can you change that location later without rebuilding the platform?
Choose the location, not just the provider
Many OEMs hold data covered by customer contracts, national requirements, or sector-specific rules. Some customers want data in a specific country. Others want it hosted on their premises, while some are comfortable using a hyperscaler. A single hosting model will rarely meet every requirement.
A cloud-native platform built on Kubernetes gives you room to answer each case differently. The same platform can run with a local provider, on-premises, or with a hyperscaler. You can decide where fleet data lives, customer by customer if you need to, without maintaining separate products.
Why open source matters for predictive maintenance systems
Kubernetes is open source and supported by a broad ecosystem, which means the platform isn’t tied to one provider’s proprietary services. That is the real meaning of “deploy anywhere”. The workloads, configuration, and deployment logic remain portable because they rely on a common foundation rather than a single vendor’s managed add-ons.
The trade-off is straightforward – portability takes discipline. Every proprietary service you adopt for convenience, such as a managed queue or a vendor-specific database, adds a small anchor. A sovereign architecture is mostly the sum of many small decisions to avoid those anchors where it counts.
Moving later should not take years
Portability has value only when migration is realistic. Infrastructure changes often expose the gap between intention and reality. a provider raises prices, a customer demands local hosting, or a policy shifts, and the “portable” platform becomes a two-year migration project.
This is the gap our NoviArc migration engine is designed to address. If you need to move to different infrastructure, a managed migration takes about a month rather than years. We treat that as a design target for the whole platform: when moving is cheap and practical, the choice of where to host stops being a one-way decision.
A practical test: ask your team how long it would take to move your telemetry platform to another provider and which components would break. If the honest answer is “we don’t know”, that is your first finding. Explore NoviArc to see how managed migration works.
Move your platform in weeks, not months
Explore NoviArc
Dashboards vs. a real data layer
Most predictive maintenance projects start with a dashboard. Sensor readings and other equipment data appear in charts, thresholds generate alerts, and someone monitors the screen. This may work for a small number of machines. At fleet scale, however, the approach breaks down because the underlying architecture cannot support predictive analytics.
Alert fatigue is a design problem
Combining raw sensor data with fixed thresholds creates noise. A vibration reading that signals a problem for a machine in one duty cycle may be normal for another, because machine-specific methods matter: vibration sensing often fits rotating equipment, while oil or sound analysis can be better for slower assets.
Set the threshold tightly enough to catch early warning signs, and it generates constant alerts. Relax it, and you risk missing shifts in equipment behaviour that help teams detect anomalies before failures escalate. Service teams quickly learn which alerts they can ignore, increasing the risk that they will also overlook a critical one.
Further threshold tuning will not solve the underlying problem. The problem is that the alert has no context: no operating history, no knowledge of which parts are in stock, no link to a service plan. Without a clear path to action, it’s simply another notification.
What a proper data layer looks like
A data layer that supports maintenance decisions consists of three connected stages:
- Ingestion and normalisation – telemetry arrives from many different generations of machines through various protocols and gateways, often with gaps and inconsistent units. The platform has to collect data from sensors, meters, and business systems, then clean, align, and store it so readings can be compared across machines, operating conditions, and duty cycles. Without this, every downstream model learns from inconsistent data.
- Integration with ERP and CMMS – many dashboards stop here, just as the data begins to deliver operational value. A prediction becomes useful when it connects to your installed base, maintenance history, spare-parts availability, and technician schedules. In practice, this means integration with systems such as SAP, which is the reference integration for our platform. Context from these systems also makes predictions better: knowing that a component was replaced last month changes the meaning of its latest reading, helps establish performance indicators for normal behaviour, and gives teams clearer visibility into asset health.
- The closed loop – the intended output is not another alert, but a maintenance action. A prediction triggers a work order, the right part is allocated, a technician is scheduled, and the outcome flows back as feedback. This supports maintenance scheduling and helps teams schedule maintenance where it is actually needed. Did the predicted failure occur? Was the part actually worn? That feedback improves the model over time and distinguishes a monitoring tool from an integrated maintenance system.
What to evaluate in your own architecture
- Can you trace every alert back through the maintenance process to the raw data, the model version, and the rule that generated it?
- Does each prediction create a work order automatically, or must someone transfer the information manually after predictive maintenance analysis joins telemetry with maintenance history from the ERP or CMMS?
- Does the outcome of each service visit feed back into the model?
- Which failure modes should you prioritise? Start where failures are frequent, costly to recover from, and genuinely predictable from the signals you have.
That final question is easy to overlook. Predicting everything is not the goal. Focusing on a small number of valuable use cases, and closing the feedback loop properly, usually delivers more value than broad coverage without effective follow-through.
Reactive vs. predictive maintenance. Why does the “double trip” costs more than you think?
Read the article
AI should advise, not control
Machine learning belongs in a predictive maintenance platform as part of a broader data driven maintenance strategy. The critical question is how much authority it should have.
- Identify faults and potential failures? Yes. AI is well suited to predictive maintenance analysis and analysing equipment data to flag emerging issues.
- Schedule repairs automatically? Usually yes, if your workflow allows predictions to trigger planned work orders or recommended repair windows.
- Shut equipment down automatically? Usually no. In most industrial settings, shutdowns affect safety, quality, and throughput and should stay under human control, with predictive maintenance work focused first on the maintenance process areas where failures are frequent, costly, and predictable.
The design: predict, decide, act with machine learning
In our architecture, the model’s job is to estimate risk and present the recommendation. A person then reviews it and decides what to do. Only then is a part ordered and a technician visit scheduled. The model never commands the machine.
Why this technical separation matters
This is more than a precaution. Keeping AI in an advisory role keeps machine learning outside the safety-control loop – the part of the system responsible for protecting people and equipment. That loop relies on deterministic, verifiable logic for good reason. Machine learning models are probabilistic. They can drift as conditions change, and their behaviour in unusual situations is hard to prove in advance.
If a model could act directly on a crane or an entrance system, you would need to demonstrate that it behaves safely in every edge case. That is a very high bar, and it’s not an appropriate place to introduce avoidable probabilistic behaviour. With an advisory design, a wrong prediction costs you an unnecessary inspection or a missed early warning, but it can’t directly command the machine to enter an unsafe state. This risk is limited through architecture rather than left to assumption.
There’s a practical benefit as well. Human-reviewed recommendations can build trust among service teams and they give you a natural audit trail: what the model suggested, who decided, and what happened next.
A useful rule: if a model’s output can change how a machine behaves in real time, treat it as part of the safety system and hold it to that standard. Otherwise, keep it advisory and separate from the safety-control loop.
Built to recognised security & safety standards
Security in industrial software is often described through features: encryption, access control, and monitoring. These features matter, but they are only the visible layer. The processes used to build, maintain, and operate the software are just as important.
IEC 62443 and IEC 61508 as engineering practice
We build the platform to two established standards, treating them as good engineering practice for predictive maintenance systems used on critical assets.
- IEC 62443 addresses cybersecurity for industrial automation and control systems. IEC 62443-4-1 defines requirements for a secure product development lifecycle, covering activities from threat modelling and secure design to vulnerability and patch management. Other parts of the series address system-level risk assessment and technical security requirements.
- IEC 61508 covers functional safety. It shapes how we think about the boundary between advisory functions and anything that touches safety, which links directly back to the AI design described above.
The value of building to a standard is that it makes security repeatable. A defined process, tested and documented, is easier to defend to a customer’s security team than a collection of standalone features.
How this supports EU compliance
Several EU regulations now touch predictive maintenance software. We mention them briefly because the argument of this article is that sound architecture meets most of them naturally.
- Cyber Resilience Act (CRA): Establishes cybersecurity requirements for products with digital elements, including secure development and vulnerability handling. Development practices aligned with IEC 62443 can provide a strong foundation for meeting the relevant requirements.
- NIS2 Directive: Strengthens cybersecurity risk-management and incident-reporting obligations for organisations in scope, including measures relating to supply chain security. Clients affected by NIS2 are likely to examine their suppliers’ security practices closely.
- Machinery Regulation: Establishes health and safety requirements for machinery, including provisions relevant to software and safety-related AI functions. Keeping AI advisory and separate from the safety-control loop helps maintain a clear boundary between predictive recommendations and safety functions.
- EU Data Act: Gives users of connected products rights to access and share data generated through their use of those products. A platform that provides control over hosting and data flows may make it easier to fulfil relevant data-access requests than one tied to a single provider.
None of this replaces legal advice, and the details and application dates differ by regulation, so check them for your products with your legal team. The broader point is that an architecture designed around data sovereignty, advisory AI, and standards-based security doesn’t need to be redesigned each time a new rule arrives.
Key takeaways
- Treat infrastructure as a strategic decision – choose a portable foundation and test how easily you could migrate. Your hosting model should remain a choice you can revisit.
- Design for action, not for alerts – connect data ingestion to your ERP or CMMS. Build a closed feedback loop so that relevant predictions lead to action and service outcomes inform future models. Done well, this creates measurable cost savings.
- Keep AI advisory – let the model predict and a person decide what action to take. This limits the model’s authority and keeps machine learning outside the safety-control loop.
- Use standards to guide engineering – IEC 62443 and IEC 61508 provide a repeatable framework for cybersecurity and functional safety. They can also support readiness for the Cyber Resilience Act (CRA), NIS2 Directive, Machinery Regulation, and EU Data Act.
Where to start?
If you’re unsure how your current architecture measures up, a good first step is a readiness audit. Assess where your fleet data lives today, how it moves between systems, how predictions turn into maintenance action, whether the current setup can reduce unplanned downtime and support better maintenance scheduling, and which standards your platform follows. The result is a clear picture of the gaps and a prioritised plan for closing them.
Book a readiness audit using the contact form below to review your predictive maintenance architecture and the predictive maintenance solutions it relies on, or explore NoviArc if infrastructure portability is your immediate priority.
FAQ: predictive maintenance data
It means you can choose where fleet data is stored and processed, and change that location later without rebuilding the platform. Many OEMs hold data covered by customer contracts, national requirements, or sector-specific rules, and a single hosting model rarely meets every requirement.
Kubernetes is open source and supported by a broad ecosystem, so the platform isn’t tied to one provider’s proprietary services. The same platform can run with a local provider, on premises, or with a hyperscaler. You can decide where fleet data lives, customer by customer if needed, without maintaining separate products.
With a managed migration through the NoviArc migration engine, the process takes about a month rather than years. A useful first test is to ask your team how long it would take to move your telemetry platform to another provider, and which components would break.
Fixed thresholds on raw sensor data ignore context, so a reading that signals a problem in one duty cycle may be normal in another. Tight thresholds generate constant alerts, while relaxed ones risk missing failures. By contrast, preventive maintenance follows a fixed schedule for tasks, which can miss the operating context that predictive systems use. A data layer that connects data ingestion to your ERP or CMMS and closes the loop with a work order gives each alert a clear path to action.
Machine learning models are probabilistic, can drift as conditions change, and are hard to verify in unusual situations. In an advisory design, the model estimates risk, a person decides, and only then is a part ordered and a technician scheduled, which lets maintenance teams act on recommendations without giving AI direct machine authority. A wrong prediction can then result in an unnecessary inspection or a missed early warning, but it can’t directly command the machine into an unsafe state.
The main ones are the Cyber Resilience Act, NIS2, the Machinery Regulation, and the EU Data Act. An architecture built around data sovereignty, advisory AI, and standards such as IEC 62443 and IEC 61508 can support readiness for all four. Application dates and details vary by regulation, so check with your legal team how each one applies to your products.
arrow_circle_rightCONTACT US
Start with a readiness audit
arrow_circle_right OUR ARTICLES